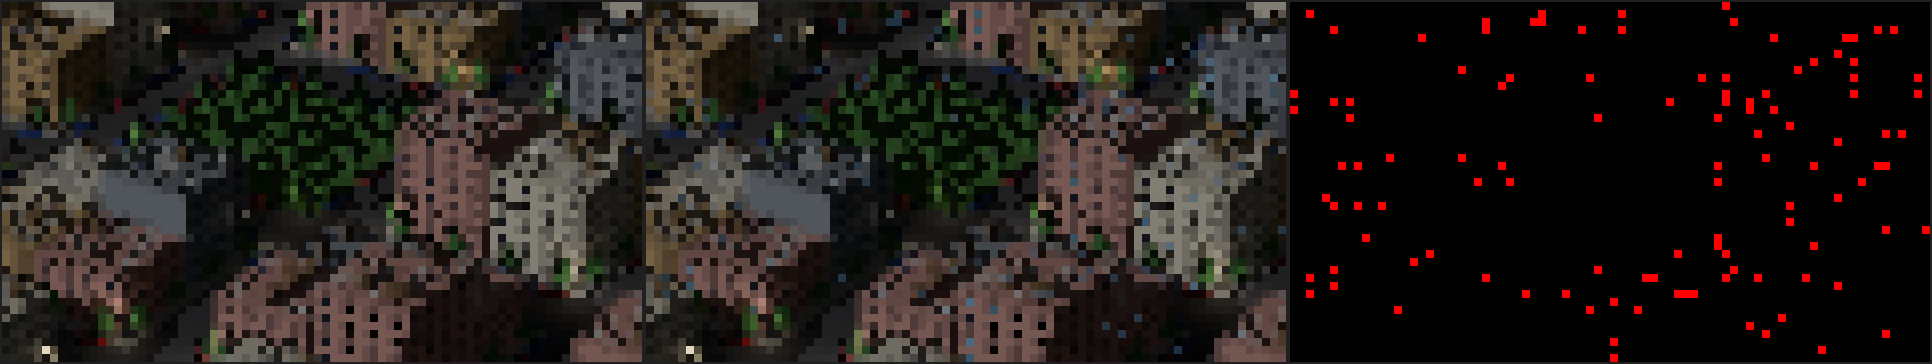Praxis · M3 · ticket #296 · prototype branch prototype/visibility-b

What a visibility pre-pass buys on town

ADR 0019 chose a forward main pass and said when to doubt it: past 6 ms of GPU on a Reference scene, two other shapes are prototyped on that scene before anything changes. town read 9.8 ms, so #296 built option B: today's pass plus a record of which triangle won each sample, and a compute pass that cuts the lit pass's draw down to those triangles. The prototype works, draws A's image, and reads 13.2 ms. Getting there turned up something the standard model of a rasterizer rules out: on the M4 Pro, which samples a triangle covers under a pixel depends on the triangles drawn beside it. This guide covers what B builds, how a prefix sum compacts a draw without changing its order, the coverage finding and the experiments that pinned it down, the Meshlet granularity that works around it, the measurement, and where that leaves the gate. Two live demos flip a sample's owner as a neighbour is drawn or not, and cut the new passes' cost down to nothing to see where the gate lands.

Provenance. #296 asked for option B on town, as ADR 0019's reopen clause requires once the gate is past 6 ms. The prototype lives on branch prototype/visibility-b in two commits: 56803ee adds the Render switch, the visibility ID pass, the visibility pass and their tests; 5bb7abd bounds the scan to the words the draw reaches. Its code is src/render/visibility_pass.rs, src/render/shaders/visibility.wgsl and visibility_prepass.wgsl, with changes to main_pass.rs, targets.rs, renderer.rs and src/gpu/mod.rs; its tests are renderer.rs's the_visibility_prepass_* and tests/visibility_prepass.rs. The figures are from praxis bench <dir> town at 2560×1440 with 4x MSAA, 248 warm-up and 1,800 measured frames, release, Apple M4 Pro, macOS 27.0.1, wgpu 30.0.1 on Metal, on 2026-10-27, in three interleaved rounds of A, B and T with no other GPU work. The research behind option B is docs/research/visibility-and-gpu-driven-main-pass.md on main.

Chapter 1 · src/render/main_pass.rs · visibility_prepass.wgsl

What option B builds

Key idea. B is A plus a record of which triangle won each sample, written by a pass of its own at depth equal, and a compute pass that cuts the lit pass's draw down to the triangles that record names.

Option A rasterizes each surviving triangle twice: once into depth, once at depth equal to shade. The second raster still runs every triangle of the frame's draw through the vertex stage and the rasterizer, including the many that own no sample at all. B records which triangle each sample shows, and the lit pass draws only those.

The record is a visibility buffer in the narrow sense: one ID per sample, nothing else. The ID is the triangle's primitive index, which the fragment stage gets as @builtin(primitive_index): the triangle made of the draw's indices 3n, 3n+1 and 3n+2 is n. Because culling builds the frame's draw as one indexed draw in slot order (Instance Culling Explained), n names a triangle of that draw directly, and 3n is where its indices sit in the packed index buffer. No instance ID is needed: the draw is one instance. wgpu exposes the builtin behind its PRIMITIVE_INDEX feature, which the M4 Pro has; the device requests it beside the Capability floor (ADR 0021) wherever the adapter has it, and the floor itself does not hold it, an owner decision still pending.

The ID pass's fragment shader is a single line:

@fragment
fn fs_visibility(@builtin(primitive_index) triangle: u32) -> @location(0) vec2<u32> {
    return vec2<u32>(triangle & 0xffffu, triangle >> 16u);
}

The two halves are there because the target is 4x MSAA, and R32Uint has no multisampling among WebGPU's guaranteed format features; Rg16Uint does. At 2560×1440 with four samples the IDs take 58,982,400 bytes, the figure the research doc computed for a 32-bit ID. The target is cleared to 0xffff in both halves, an ID of no triangle, and stored for the compute pass that reads it. It lives in the targets module beside the depth target, so a resize recreates it and the bind groups that read it.

The frame with the switch on

Everything B adds sits behind one Render switch, visibility_prepass, with three values: Off, as Praxis ships, Meshlets and Triangles, the two granularities chapters 3 and 4 are about. praxis bench and praxis capture take it as --visibility-prepass and --visibility-prepass-triangles. With it on, phase two's depth always has a pass of its own, as it does with shadow rays on, so the depth target holds every Instance's depth before the IDs are drawn:

The frame's passes with visibility_prepass on, in the order the frame records them (TIMED_PASSES, src/render/renderer.rs)

  1. culling phase one
  2. Froxel pass
  3. depth pre-pass
  4. depth pyramid
  5. culling phase two
  6. phase-two depth pass
  7. visibility ID pass
  8. visibility pass
  9. shadow mask pass
  10. lit pass, the compacted draw
  11. tonemapping
new: a render pass, then a compute pass its own pass whenever shadow rays or the switch are on draws the compacted draw instead of the frame's draw
The visibility ID pass draws the frame's draw again, both phases, at depth Equal with writes off: the lit pass's own depth state, so the IDs name the triangles the lit pass would show. Chapter 3 is about why they are not written in the depth passes themselves. The two new passes join Frame stats as visibility_id_pass and visibility_pass, making 14 timed passes, and so grow every Baseline's gpu_memory_bytes by 224 bytes of readback buffers; on the branch, praxis compare refuses every Baseline until it is re-recorded.

The visibility pass, a compute pass, turns the IDs into a draw: it marks the triangles the IDs name, counts the marks, and copies each marked triangle's three packed indices, in order, into a compacted index buffer with the indirect arguments to draw them. The lit pass then binds that buffer and that argument buffer in place of the frame's. Nothing in its shading changes: it still rasterizes at depth equal, reads the Froxel lists and the shadow mask, and resolves its 4x MSAA colour. Chapter 2 is about the counting and copying.

Chapter 2 · src/render/visibility_pass.rs · visibility.wgsl

Compaction by prefix sum

Key idea. A bit per triangle, a scan over the bits, and a copy in bit order give each marked triangle its place without changing the draw's order, which on the M4 Pro would change the derivatives some pixels sample their textures with.

A compaction takes a list with some items marked and produces the marked items packed together. The fast and tempting way is an atomic counter: each marked item takes the next slot. The order the slots are taken in is then whatever order the GPU's threads happened to run in, and it changes from run to run.

Praxis never builds a draw that way. The culling pass builds the frame's draw in slot order because, on the M4 Pro, which triangles precede others in a draw changes the implicit derivatives of some pixels, so their texture lookups pick a different mip level, so a Golden captured twice would differ (Instance Culling Explained). The compacted draw inherits that rule: it keeps the frame's draw's order exactly, and gets each triangle's place from a prefix sum instead of a counter. In four dispatches, all in one compute pass:

  • Mark. A workgroup per 8×8 tile of pixels, an invocation per pixel, loads its four samples' IDs together (Metal's compiler does not unroll a loop over them) and sets a bit per triangle with atomicOr in a buffer of 32-bit words, one bit per triangle the frame's draw can hold. A sample whose ID equals the sample before it marks nothing again. Atomics are fine here: a bit set twice is set.
  • Count by word, scan by block. offset_words runs a workgroup per block of 256 words. Each invocation counts its word's bits with countOneBits, and the block runs the shared scan.wgsl, the Hillis and Steele scan the culling pass also uses, to give each word the number of marked triangles in the earlier words of its block, an exclusive prefix sum. The block's own total goes in a second array.
  • Scan the blocks. One workgroup, offset_blocks, scans the block totals into block offsets and writes the compacted draw's indirect arguments: an index count of three per marked triangle, one instance, nothing else.
  • Copy. compact_triangles runs an invocation per word again. Its slot is the block's offset plus the word's; it walks the word's set bits from the lowest with firstTrailingBit, copies the triangle's three packed indices to the slot, and moves on.
var bits = atomicLoad(&triangle_bits[word]);
var slot = triangle_offsets[word_capacity + block.x] + triangle_offsets[word];
while bits != 0u {
    let triangle = 32u * word + firstTrailingBit(bits);
    for (var corner = 0u; corner < 3u; corner++) {
        compacted_indices[3u * slot + corner] = packed_indices[3u * triangle + corner];
    }
    slot += 1u;
    bits &= bits - 1u;
}

Within a word the bits are walked in order; across words and blocks the prefix sums put earlier words first. So the compacted draw is the frame's draw with the unmarked triangles removed and nothing moved, whatever order the GPU ran the invocations in. The lit pass draws it in one call: draw_calls reads 5 with the switch on against A's 4, the ID pass's draw being the fifth.

The buffers, and what the scan costs

The compacted index buffer holds what the frame's draw can hold, 225 indices, 134,217,728 bytes; it is the largest of B's additions after the IDs. The triangle bits take 1,398,104 bytes, their offsets 1,403,568, and the compacted draw's arguments 20. Chapter 4's record bits add 131,072. Each is a GPU buffer the pass owns, so each joins gpu_memory_bytes.

The branch's second commit bounds the scan and the copy to the words the frame's draw actually reaches, instead of the full capacity. That moved the gate by about 40 µs. So the visibility pass's time, 3.4 ms at Meshlet granularity in chapter 5, is not the scan: it is the mark over 3.7 million pixels, four texture loads and up to four atomics each, and the compaction's writes.

Chapter 3 · tests/visibility_prepass.rs · the sub-pixel tilted quads

Coverage depends on the neighbour

Key idea. On the M4 Pro, which samples a triangle covers under a pixel depends on the triangles drawn beside it, so a draw of only the triangles that own a sample loses samples along coplanar shared edges, and no depth tie rule brings them back, because the missing fragments are never generated.

The rasterizer decides, for each of a pixel's four sample positions, whether it lies inside a triangle's three edges. Covered samples are depth-tested one by one; the fragment shader runs once for the pixel and its result lands in the covered samples that passed. In the standard model that decision depends on the triangle's vertices and the sample's position, and on nothing else.

That model is what makes a coverage-based compaction sound in principle. Two triangles that share an edge are watertight: the fill rule gives a sample exactly on the edge to one of them, so along the edge every sample is covered once, none twice, none missed. And a triangle drawn alone covers exactly the samples it covered beside its neighbour, because the neighbour was never part of the decision. If an ID pass records which triangle owns each sample, then drawing exactly those triangles must put the same fragment in every sample, and the image cannot change.

The first shape, and what it drew

The research doc and the ticket describe the cheapest shape: write the IDs in the depth pre-pass itself, depth Greater with writes on, so the record comes free with the depth. Built that way, town differed from A at 176 to 4,335 pixels per frame over the eight checked frames at 640×360 (frames 59, 300, 500, 700, 900, 1200, 1500 and 1800), the pixels scattered over distant, sub-pixel geometry: the wires, the far cubes. Each experiment below is a run of all eight frames.

ExperimentResult
Depth GreaterEqual, so ties go to the later triangleNo difference
The visibility pass run twice in a frame, a race testNo difference
A separate ID pass at depth Equal: exactly the lit pass's depth state and draw orderStill 180 to 4,276 pixels
Every triangle forced marked0 pixels: the compaction is right, the marks are incomplete
Each ID's previous triangle marked tooMost differences gone
Each ID's neighbours at ±2 marked tooNearly all gone

The last two rows say what is missing: the index neighbours of the triangles that own samples, which in town's cubes and wires are the other triangle of the same quad face. The compaction drops a quad's second triangle because no sample names it, and with it gone the first triangle stops covering some of the samples it owned.

Reading the coverage back

To see that directly, a unit test encoded each fragment's sample_mask, the four bits of the pixel's samples the fragment covers, into its ID, and read the IDs back at the pixels that differed: 10,000 quads 0.3 m wide at 40 m, tilted, at 256×256, where 527 pixels differed. The same triangle, drawn in the full draw and then in the compacted draw without its quad partner, covered fewer samples the second time:

TriangleSamples covered in the full drawAlone, without its quad partner
157410 and 1 (mask 0011)0 (mask 0001)
152970, 1 and 2 (mask 0111)0 and 2 (mask 0101)
151490, 1 and 2 (mask 0111)0 (mask 0001)

Nor is it the depth test rejecting those samples. With the lit pass's compare changed from Equal to GreaterEqual or LessEqual, the same 527 pixels differed. A sample a depth test rejects would come back under a looser test; these do not, so the fragments for those samples are never generated. The rasterizer, drawing the triangle alone, decides that it does not cover them.

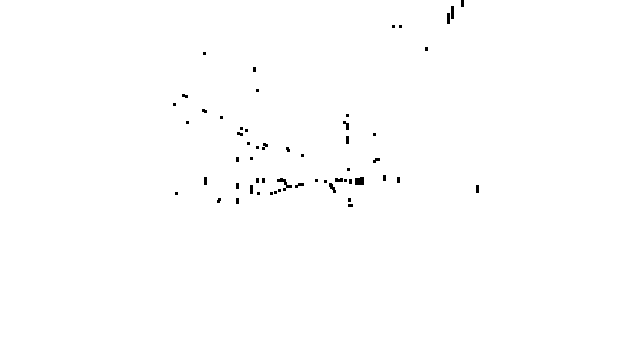
Why this GPU does that is not documented and this guide does not guess. What the readings establish is narrower and enough: on the M4 Pro, coverage along a coplanar shared edge is a property of the pair, not of each triangle, so a draw that keeps one triangle of a pair draws a different image from a draw that keeps both. That rules out the free version of B, the IDs written in the depth pre-pass, and it also rules out the honest version at triangle granularity, the separate pass at depth equal, which still lost 180 to 4,276 pixels. The ignored test on the branch prints the losses per frame at triangle granularity: 180, 168, 1,216, 3,811, 4,256, 4,265, 4,250 and 4,276 pixels at frames 59, 300, 500, 700, 900, 1200, 1500 and 1800. The images are linked in the reading list: black marks where triangle granularity lost samples, and an 8x crop of frame 1800 beside A.

sample owned by triangle 1 sample owned by triangle 2, the neighbour sample no triangle covers lost: covered beside the neighbour, not alone

Live demo. A 6×4 pixel grid with the standard four-sample pattern, under a thin tilted quad split along its diagonal, the shared edge. Drawn whole, every sample inside the quad belongs to exactly one triangle, as the fill rule says. Drawn alone, in this page's model of the readings above, triangle 1 covers a sample only if it lies more than a small distance inside the shared edge, so the samples nearest that edge are lost. The width of that band is this page's choice to make the effect visible; the M4 Pro's rule is not known, only that triangles 15741, 15297 and 15149 covered fewer samples alone. Slide the quad to see different samples flip.
Chapter 4 · VisibilityPrepass::Meshlets · record_bits

Meshlet granularity

Key idea. Compacting every triangle of any Meshlet one of whose triangles owns a sample keeps each triangle's neighbours in the draw, and reproduces A exactly on every frame checked, at the cost of drawing more triangles than own a sample.

If the lost samples come from missing neighbours, keep the neighbours. The unit the frame's draw already groups triangles in is the Meshlet: a small group of one Primitive's triangles, bounded in vertex and triangle count, that the GPU draws as a unit and can cull as one. A quad's two triangles are almost always in the same Meshlet.

Each packed index already carries its Meshlet: the record's number sits in the bits above the vertex, so packed_indices[3 × triangle] >> MESHLET_VERTEX_BITS is the record any triangle was drawn with. At Meshlet granularity the mark step sets a bit per record instead of per triangle, in a buffer of 220 bits, 131,072 bytes. Then, before offset_words counts a word, it rebuilds the word's 32 triangle bits from the records: a triangle is marked if its Meshlet is. From there the scan and the copy run unchanged, so the compacted draw holds every triangle of every Meshlet some sample shows, in the frame's order.

That reproduces A: 0 differing pixels on all eight town frames, and 0 on the tilted quads that lost 527 at triangle granularity. The shader's own comment states the limit of the claim: it holds "on the Reference scenes checked". A quad whose two triangles fell into different Meshlets would lose samples again, and nothing in the pass prevents that; the scenes checked did not show it.

The tests

  • A hidden quad is excluded. A near quad hides one quad wholly and leaves another apart: of the six triangles the frame draws, four are compacted, in the first frame, where phase two draws every Instance, and in the next, where phase one draws those visible before. The image equals the switch-off image.
  • Phase two's triangles are marked past phase one's. In the frame a lower triangle enters the view, phase one draws the upper one and phase two the lower, and the compacted draw holds both.
  • 20,000 triangles across scan blocks. 10,000 quads in a grid, all in view, compact every triangle in order, past one block of 256 words.
  • A triangle one sample alone shows. A strip 0.15 pixels wide placed over the second of the four sample positions and no other is compacted from that sample.
  • The 7,871 sub-pixel tilted quads draw the switch-off image at Meshlet granularity.
  • town at eight frames. tests/visibility_prepass.rs captures the frames with the switch off and at Meshlet granularity and requires every pixel within the Goldens' tolerance, 1 step of 8 bits; with PRAXIS_VISIBILITY_IMAGES set it writes A, B and their difference for a PR, the all-black differences in the reading list. Its ignored companion prints triangle granularity's losses, chapter 3's list.
Chapter 5 · praxis bench <dir> town · three rounds

The measurement

Key idea. B's gate reads 13.2 ms against A's 9.7 and T's 11.5; the lit pass saves 2.9 ms with rays on, but the two new passes cost 5.5, and even with them free the gate would sit at about 7.0 to 7.7 ms against 6.

The bench renders town twice per run, shadow rays on and then off, and ADR 0019's gate comes from the rays-off run (Frame Timing Explained). Three rounds, each A then B then T, interleaved so that drift affects all three alike, at a load average of 3.9 to 5.3 and no other GPU work. The table gives the medians of the median round; across rounds the gate spread from 9,652 to 9,672 µs for A, 13,157 to 13,194 for B and 11,512 to 11,533 for T, so the differences below are far outside the noise.

town, medians, µsA: switch offB: MeshletsT: Triangles
ADR 0019's gate, rays off (p95)9,656.7 (10,048.3)13,173.9 (13,641.2)11,527.7 (11,970.1)
Over A; ratio—+3,517; 1.364+1,871; 1.194
GPU frame, rays on (p95)13,688.0 (14,201.7)17,031.6 (18,415.2)15,361.4
lit_pass8,802.15,916.0 (−2,886; 0.672)5,767.4
visibility_id_pass—2,079.52,083.2
visibility_pass—3,436.42,434.0
depth_prepass1,754.5——
culling phase one, phase two1,515; 898——
shadow_mask_pass4,701.85,426.6 (+725)—
tonemapping3,870.0—4,739.9
gpu_memory_bytes616,555,496812,688,388 (+196,132,892)—
draw_calls45—

The pass times are from the rays-on run, the gate from the rays-off one, and a dash means the figure was not kept. Two readings move for no reason of their own: B's shadow mask pass gains 725 µs and T's tonemapping reads 4,739.9, but neither traces more rays nor maps more pixels. Metal runs passes side by side, and a pass's reading stretches over work that is not its own, which is why a frame's time is a span and not a sum. B's memory grows by exactly its buffers: the IDs 58,982,400, the compacted indices 134,217,728, the triangle bits 1,398,104, their offsets 1,403,568, the record bits 131,072 and the compacted draw 20.

The lit pass does get cheaper: 5,916 µs against 8,802 with rays on, a saving of about 2.9 ms. The ID pass costs 2,080 and the visibility pass 3,436, so B spends 5.5 ms to save 2.9. T, which loses samples and so is not a candidate, spends 1 ms less in its visibility pass than B, since it marks and copies fewer triangles, and its lit pass is 150 µs cheaper; it is in the table only to bound what triangle granularity would have bought had it drawn the right image.

If the new passes were free

Metal overlaps passes, so subtracting pass times from a span is arithmetic, not measurement; it bounds, it does not predict. B's gate less its two new passes is 13,174 − 2,080 − 3,436, about 7,660 µs; T's is 11,528 − 2,083 − 2,434, about 7,010. Even with the IDs written and the compaction done for free, the lit pass's saving leaves the gate at about 7.0 to 7.7 ms against 6. And writing the IDs for free, in the depth pre-pass, is exactly what chapter 3 forbids on this GPU: a raster pass of the frame's draw, which reads 1.75 ms as the depth pre-pass, is the floor of any further pass that touches every triangle, and the ID pass reads 2.08 ms, in line with the research doc's probe, where primitive_index made an ID pass 19 to 24% slower than one writing the instance alone.

the gate less the two new passes visibility ID pass visibility pass 6 ms, ADR 0019's gate

Live demo. The measured gates, 9,656.7, 13,173.9 and 11,527.7 µs, with B's and T's new passes drawn as the segments at the end of their bars, at their rays-on medians. The slider scales those two segments down; the rest of each bar is the gate less the two passes, this page's subtraction. At zero, B reads about 7.66 ms and T about 7.01: still past the line, and still past A's lit pass alone. It is arithmetic over a span Metal fills with overlapping passes, so it bounds the prototype, and predicts nothing about a different one.

For scale, the Baseline's rays-off passes inside A's gate, as Frame Timing Explained gives them: the lit pass 5.15 ms, the depth pre-pass 1.76, culling 1.52 and 0.89, the Froxel pass 0.53, the depth pyramid 0.25. B's whole saving has to come out of that 5.15, and two more raster passes of the frame's draw are in the way of it.

Chapter 6 · ADR 0019's reopen clause · #296, #297

Where this leaves the gate

Key idea. B as prototyped does not reach 6 ms on town and could not with a free ID pass on this GPU, so the clause's decision rests with the owner: keep A and move the gate, or adopt an option, each an ADR change; D's ID pass would be this one.

ADR 0019's reopen clause: past 6 ms on a Reference scene at 1440p with 4x MSAA, "B and D are prototyped on that scene before anything changes." B has been. It draws A's image at Meshlet granularity, and its gate is 1.364 times A's.

The prototype stays on its branch; nothing of it is on main, and Praxis ships with the switch off. What the clause leaves to the owner is the decision itself, and both of its answers change an ADR: keep A and move the gate, which is provisional as ADR 0013's Budgets are, or adopt an option. Two smaller decisions wait with it: whether PRIMITIVE_INDEX joins the Capability floor, which the prototype requests beside it only where the adapter has it, and the Baselines, which the two new timed passes grow by 224 bytes each and which are refused until re-recorded.

What this says about D

Option D, ticket #297, shades from the IDs in compute and does not rasterize the scene a second time, so the coverage finding does not bite it the same way: there is no reduced draw whose coverage has to match the full one. But its ID pass would be this one. The IDs it shades from have to name the triangles the depth test kept, so they are written at depth equal after a depth pre-pass, and on town that pass reads 2.08 ms before any shading. D's prototype starts from that number, and from the derivative problem the research doc describes: compute has no 2×2 quads to take texture differences across, so it works them out itself.

What the prototype adds to the record beyond its gate is the finding itself. A pass that draws a subset of a draw and expects the same image, whether to cull, to compact, or to shade in two passes, is checked against the full draw on the reference GPU, pixel by pixel, before it is believed. The ignored test and the sample-mask readings are how that check was done here, and they are on the branch for the next one.

Check yourself

Three questions on the guide's central ideas. Try each before you open its answer.

Why does drawing only the triangles that own a sample lose samples on the M4 Pro, and why does no depth compare bring them back?

On this GPU, which samples a triangle covers along a coplanar shared edge depends on whether the triangle on the other side of the edge is in the draw. Drawn with its quad partner, triangle 15741 covered samples 0 and 1; drawn without it, only sample 0. The lit pass with GreaterEqual or LessEqual in place of Equal drew the same 527 differing pixels, so the missing samples are not fragments the depth test rejected: the rasterizer never generated them. Keeping whole Meshlets keeps the partner in the draw, and reproduces A exactly on every frame checked.

Why does the compaction get each triangle's place from a prefix sum over bits rather than from an atomic counter?

An atomic counter hands out slots in the order the GPU's threads happen to run, which changes from run to run. On the M4 Pro, which triangles precede others in a draw changes the implicit derivatives some pixels sample their textures with, so a Golden captured twice would differ. Counting each word's bits, scanning the counts within each block of 256 words and then across blocks, and walking each word's bits from the lowest gives every marked triangle the number of marked triangles before it in the frame's draw: the same order as the frame's draw, whatever order the invocations ran in.

B's two new passes read 2,080 and 3,436 µs. If both were free, would B reach the 6 ms gate on town?

No, by this page's arithmetic. B's gate is 13,174 µs; less its two new passes it is about 7,660, and T's, which loses samples, about 7,010 by the same subtraction. The lit pass saves about 2.9 ms with rays on, and the saving has to come out of A's rays-off lit pass of 5.15 ms, but the gate also holds culling, the depth pre-pass and the pyramid. And the only way to make the ID pass free, writing the IDs in the depth pre-pass, is what the coverage finding rules out on this GPU; a separate raster pass of the frame's draw costs at least what the depth pre-pass costs, 1.75 ms.

Reference

Reading list

Grouped by source, each with what it is good for here. Links into the prototype are pinned to 5bb7abd, the branch's head; links into main to ba043f3.

This ticket

In the repo

The code, on the branch

Images

Papers and talks

Books

  • Real-Time Rendering, 4th ed.: ch. 5 Shading Basics, on sampling and MSAA; ch. 23 Graphics Hardware, on rasterization and its tie rules
  • Foundations of Game Engine Development, vol. 2: ch. 9 Visibility and Occlusion

Earlier volumes

Reference

Glossary

Where CONTEXT.md defines a term, the definition here and in the tooltips is its own at ba043f3, or a quoted part of it; the gate adds what ADR 0019 says of it. Visibility buffer follows the earlier volume; primitive index, sample coverage and compaction are this guide's, in the sense WGSL, WebGPU and Blelloch give them.

Render switches
The variants a Renderer is created with and keeps: whether Instances are culled, whether lights are culled into Froxels or all reach every pixel, whether shadow rays are traced, whether a pass counts each lit pixel's point lights, and the form the crowd scene's deforming meshes take in the TLAS. Their defaults are what ships; scene content such as ambient and background is not a switch. The prototype adds the visibility pre-pass, off by default.
Meshlet
A small group of one Primitive's triangles, bounded in vertex and triangle count, that the GPU draws as a unit and can cull as one.
Frame stats
What one frame cost, measured by the engine itself: among much else, CPU time per system and stage, GPU time per pass, the GPU frame total and ADR 0019's gate, draw calls, Instances and triangles drawn, bytes uploaded and GPU memory.
ADR 0019's gate
From the start of culling phase one to the latest end of the passes up to the lit pass, with shadow rays off; its median over a Reference scene's camera path is judged against 6 ms.
Baseline
The recorded measurements of a Reference scene on one adapter: the reference machine, where Budgets are judged against it, or CI's lavapipe, where only its counters are judged.
Budget
A numeric limit on one metric of a Reference scene (CPU ms, GPU ms, GPU memory, Input latency) that a change must not regress. Counters such as draw calls and bytes uploaded are held to their Baselines instead.
Reference scene
A Scene paired with a fixed camera path and injected time, so that every run produces the same frames. Used for Goldens and Baselines.
Golden
A committed image that a Reference scene must reproduce within tolerance.
Visibility buffer
A 4-byte triangle and instance ID per sample, written by a pre-pass, from which later passes rebuild the surface each pixel shows. B only reads it to choose what the lit pass draws; D shades from it.
Primitive index
A fragment stage builtin: the index of the triangle the fragment belongs to within its draw, so the triangle made of indices 3n, 3n+1 and 3n+2 is n. WGSL's @builtin(primitive_index); wgpu exposes it behind the PRIMITIVE_INDEX feature.
Sample coverage
Which of a pixel's MSAA samples a triangle covers: the samples whose positions fall inside its three edges, with a fill rule giving a sample exactly on an edge to one of the two triangles that share it. Depth is tested per covered sample; the fragment shader runs once per pixel.
Compaction
Copying the marked items of a list into a dense list that keeps their order: a prefix sum of the marks gives each marked item its place, the number of marked items before it.
Built from ticket #296, branch prototype/visibility-b at 56803ee and 5bb7abd, ADRs 0019 and 0021, CONTEXT.md and the visibility research doc on main at ba043f3, and a bench of town on the M4 Pro on 2026-10-27. The experiments in chapter 3 are the branch's own, read from its tests. Where the guide does its own arithmetic, it says so. The coverage demo is this page's model of the readings, with a band width of its own choosing; the gate demo uses the measured gates and the rays-on pass medians.